🔍 Read the full analysis: The One-Evening Journey From AI Idea To Production on ThorstenMeyerAI.com

Get hardware and tech essentials delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
TL;DR
Thorsten Meyer says he built a hand-drawn video engine in one evening and published a short test after reviewing it himself. The first full video was slow and visually weak, so his team measured frame coverage, still time and camera movement, then turned those measures into build checks. The account is a personal case study, not independent evidence that the approach will work for other projects.
Thorsten Meyer says he went from liking a hand-drawn explainer style to building and publishing a test video in one evening, then used measurements and automated checks to improve the first full-length result. In a personal account published November 6, Meyer says the rapid build was less important than the human approval, independent code review and production gates he added after the initial video proved slow and visually static.
Meyer says the project began with a video whose visual style he admired. To avoid copying it, he says he wrote down a limited set of general traits—a hand-drawn line, a continuous visual world and large numbers used as color accents—without using the original video’s drawings, assets or layouts. He says Claude built the drawing engine from scratch, using his own design system and an openly licensed handwriting font.
He describes a division of labor between two AI systems: Claude generated the code, while OpenAI’s Codex reviewed it and attempted to find problems. Meyer says five findings from the initial review were fixed that evening. He says each fix was paired with a test that failed against the earlier code, a practice intended to show that the test could detect the original problem rather than merely pass after a change.
Meyer says he watched a roughly one-minute test video and personally approved it for publication that evening. The next morning, however, the first full video in the new style seemed to him slow and boring, with excessive white space, icons that did not support the narration and drawings that stopped moving once complete. He says that version remains online unchanged as an example of what did not work.
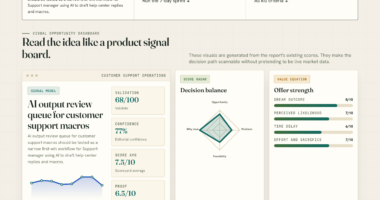
Infographic 01 · The new video look
One evening, one boring first video, one measured fix
Speed was not the point. The steps in between were: a second AI that reviews, a human who says yes, and numbers that became gates.
Share of the frame filled with content on the first three scenes after the fix. Before: 15%.
From an evening idea to a measured fix
Relative times, this week
- EveningA video I likedClean room: only a list of style traits, no drawings, assets or layouts
- Same eveningOwn engine, first reviewClaude builds; OpenAI’s Codex reviews; 5 findings fixed, each with a test that fails on the old code
- Same eveningA human says yesOne-minute test video approved and published
- Next morningFirst full video: slow and boringToo much white space, icons that did not fit, a picture that stood still
- Hours laterMeasured fix, then gatesThe first video in the improved look goes live
Source: my own build notes for the new video look, this week (engine history, review round, approval, critique, before/after measurement of the first three scenes).
Powered by Thorsten Meyer AI
How Visual Metrics Became Build Gates
The account’s practical point is that generating a working demo did not establish that the result was ready for wider use. Meyer says his team responded to the full video’s shortcomings by measuring how much of the frame contained content and how long the image remained still, rather than making repeated changes based only on taste.
On the first three scenes of the rebuilt video, Meyer reports that filled-frame coverage rose from 15% to 66%, time standing still fell from 29 seconds to zero, and camera moves increased from 3 to 27. These are figures from his own project, not an independently verified comparison or a general benchmark. He says the measurements were turned into gates: scenes judged too empty are stopped before rendering, and the build flags objects that do not illustrate the narration at that moment.
For readers using AI to make software or media, the distinction matters: a functioning output is not the same as an approved or reliable output. Meyer’s process includes review, a responsible human decision and checks intended to catch known defects before production. His account also shows that metrics can make a subjective critique more actionable, while leaving open whether these particular thresholds suit other projects.
Products Worth Considering

Logitech MX Master 4 Ergonomic Wireless Mouse with Haptic Feedback, Graphite

Apple AirPods Pro 3 Wireless Earbuds with Active Noise Cancellation

Bose QuietComfort 45 SE Wireless Noise-Cancelling Over-Ear Headphones
As an affiliate, we earn on qualifying purchases.
From Test Clip to Published Video
Meyer places the work in a broader account of taking AI-generated ideas into production. He says the one-minute test clip appeared in an article about local votes against data centers. After the next morning’s full video drew his criticism, the team rebuilt the visual approach; he says the first video using the improved look went live a few hours later, in an article about the Nasdaq’s worst day in 19 months. The source does not provide the date of that market event.
The article also describes a separate experiment involving a local model and legal questions. Meyer says Claude edited the model’s weights and that it completed 12 of 15 answers in a legal benchmark, compared with 4 of 15 before. He also says its legal score remained at zero. That result illustrates why task completion counts alone can mislead: the model answered more items, but the reported legal score did not improve. The source excerpt does not detail the benchmark’s scoring method or provide enough information to assess the experiment independently.
Meyer further recounts an earlier monitoring failure: in August, he says a guard produced about 1,300 warnings in a log that nobody read, while an alert email did not go out. The episode supports his stated focus on whether monitoring reaches a person. The source gives no further incident details, so the warning count should be treated as his account of that system, not as a general measure of AI risk.
“A demo that runs is not a decision.”
— Thorsten Meyer, in his November 6, 2026 article
What the Project Numbers Establish
The figures and outcomes are Meyer’s own reports, drawn, he says, from build notes, incident notes and experiments published on his site. The account does not include an outside audit, detailed test data, or enough information to reproduce the video measurements. It also does not establish whether the reported changes would hold across different video topics, styles or production systems.
Some specifics remain unclear in the supplied account, including the exact thresholds used to reject empty scenes, how the system determines whether an object matches narration, and how Codex’s six checks were selected. Meyer says four of six reviewer checks failed in one review round despite all 12 of the author’s tests passing; the excerpt does not identify the code or explain whether that review round concerned this video engine. The relationship between those checks and the initial five findings is also not fully detailed.
The legal-model result is similarly limited: the number of completed answers increased, but the legal score remained at zero. Without the benchmark’s rubric, answer quality and evaluation details, the completion count alone cannot establish improved legal performance. The source’s description of the project is a personal case study, not a controlled comparison of AI development methods.
Further Tests Before Broader Claims
Meyer says the visual measurements now operate as gates in the video build, so the next step in this workflow is for those checks to flag scenes before they are rendered and published. He says the improved-style video and the explanatory video accompanying the account were made using the revised approach. The source does not announce a release schedule, product launch or formal evaluation.
For readers following the work, useful next evidence would include the gate thresholds, examples of flagged scenes, and results across a larger set of videos. Details of the legal benchmark and the separate code-review findings would also help clarify what the reported tests measure. Until that information is available, the documented outcome is specific: Meyer reports a faster iteration from concept to publication, while the reliability and transferability of the method remain unverified beyond his own project.
Key Questions
What did Thorsten Meyer build?
Meyer says he built a hand-drawn video engine from scratch with Claude, using a defined set of visual traits and his own design system. He says a short test video was approved and published the same evening.
What changed after the first full video?
Meyer says the first full video had too much white space, icons that did not support the narration and images that became still. The team measured frame coverage and still time, revised the engine and turned some visual checks into production gates.
Were the reported results independently verified?
No independent verification is described in the source. The video metrics and project history are presented as Meyer’s own account, based on his build notes, incident notes and experiments.
Did the legal-model experiment improve the model’s score?
Not according to Meyer’s account. The model completed 12 of 15 answers instead of 4, but its legal score remained at zero. The source excerpt does not provide the benchmark rubric or enough detail to assess answer quality.
Source: ThorstenMeyerAI.com