TL;DR

Get hardware and tech essentials delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
OpenAI has released initial performance data for its Jalapeño inference chip, claiming up to 1.9x better efficiency and 3.6x lower latency than NVIDIA’s comparable hardware. These results are based on internal testing and have yet to be independently verified or deployed at scale.
OpenAI has announced its first measured performance results for Jalapeño, its custom inference chip, revealing significant improvements in efficiency and latency compared to NVIDIA’s hardware. The results, based on internal testing, highlight the chip’s potential to reduce serving costs and improve AI response times in datacenter environments. These findings are important for the AI infrastructure landscape, as they mark a step toward specialized silicon designed explicitly for language-model inference.
OpenAI’s Jalapeño chip was tested against NVIDIA’s Blackwell generation, specifically on inference benchmarks involving models like GPT-OSS 120B, DeepSeek R1 670B, and Kimi K2.5 1T. The tests, conducted using the publicly available InferenceX benchmark, showed Jalapeño achieving between 1.5x to 1.9x higher performance per watt, and reducing end-to-end latency by 1.7x to 3.6x. For instance, on GPT-OSS 120B, Jalapeño delivered approximately 1.9 times the peak throughput-per-watt and 1.7 times lower latency than NVIDIA’s GB200 system.
These figures suggest a meaningful efficiency gain, especially in datacenter settings where power consumption directly impacts operational costs. However, the results are based on vendor-reported data from OpenAI, not independent benchmarks, and the chip has not yet been deployed in production environments. The testing focused solely on inference tasks, with the chip designed specifically for this purpose, unlike NVIDIA’s general-purpose GPUs.
Implications for AI Infrastructure Costs
The performance improvements claimed by OpenAI indicate that specialized inference hardware like Jalapeño could significantly reduce operational costs for large-scale AI deployment. By achieving higher efficiency and lower latency, organizations can potentially lower power bills and improve response times for AI services. This development underscores a broader industry trend toward custom silicon tailored to specific workloads, which may reshape how AI infrastructure is built and scaled in the future.
Products Worth Considering
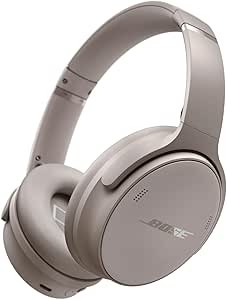
Bose QuietComfort Wireless Noise Cancelling Headphones, Sandstone

Bose QuietComfort Headphones (2nd Gen), Wireless Noise-Cancelling Over-Ear Headphones, Black

Amazon Kindle Paperwhite Signature Edition (12th Generation, 2024), 32 GB, Metallic Black
As an affiliate, we earn on qualifying purchases.
Background on Custom AI Chips and Benchmarking
OpenAI’s move to develop Jalapeño aligns with broader industry efforts to create purpose-built hardware for AI inference, driven by the rising costs and latency challenges of using general-purpose GPUs like NVIDIA’s. Prior to this, most large AI models relied heavily on GPU acceleration, with hardware performance improvements coming from software optimizations and hardware scaling. OpenAI’s internal testing on Jalapeño, conducted in late 2023, marks a notable step, but these results are preliminary and based on the company’s own measurements.
It’s important to note that the benchmarking focused on inference workloads, which are critical for deploying language models at scale. The chip’s design emphasizes minimizing data movement and optimizing for both prompt processing and token generation phases, which are key to interactive AI applications. The results are promising but require independent validation and real-world deployment to confirm their significance.
Unverified Results and Deployment Timeline
While the performance data from OpenAI is compelling, it remains unverified by independent benchmarks. The measurements are vendor-reported and conducted in controlled internal tests. Jalapeño has not yet been deployed in production environments, with full deployment expected only by the end of 2024. It is unclear how the chip will perform at scale or in real-world settings, and whether the efficiency gains will translate into significant cost savings in operational environments.
Next Steps for Validation and Deployment
OpenAI plans to begin deploying Jalapeño internally later in 2024, with broader testing to follow. Independent researchers and industry analysts will likely seek to verify the performance claims through third-party benchmarks once the chip is in use. Additionally, further development may focus on expanding the chip’s capabilities, integrating it into larger AI infrastructure, and assessing its performance across different workloads and models.
Key Questions
How does Jalapeño compare to NVIDIA’s GPUs in inference performance?
According to OpenAI’s internal tests, Jalapeño achieves up to 1.9 times higher performance per watt and significantly lower latency than NVIDIA’s Blackwell GPUs in specific benchmarks. However, these results are preliminary and based on vendor-reported data.
Is Jalapeño ready for deployment in real-world AI systems?
No, Jalapeño has not yet been deployed in production. OpenAI plans to begin internal deployment by late 2024, with broader industry validation to follow.
What makes Jalapeño different from general-purpose GPUs?
Jalapeño is a purpose-built inference ASIC designed specifically for language-model workloads. It minimizes data movement, optimizes for both prompt processing and token generation phases, and is tailored for efficiency in inference tasks.
Will these performance gains reduce AI deployment costs?
If the performance improvements are confirmed in real-world deployments, they could lead to lower power consumption and operational costs for large-scale AI services. However, the actual impact remains to be seen once the chip is in production.
Source: ThorstenMeyerAI.com