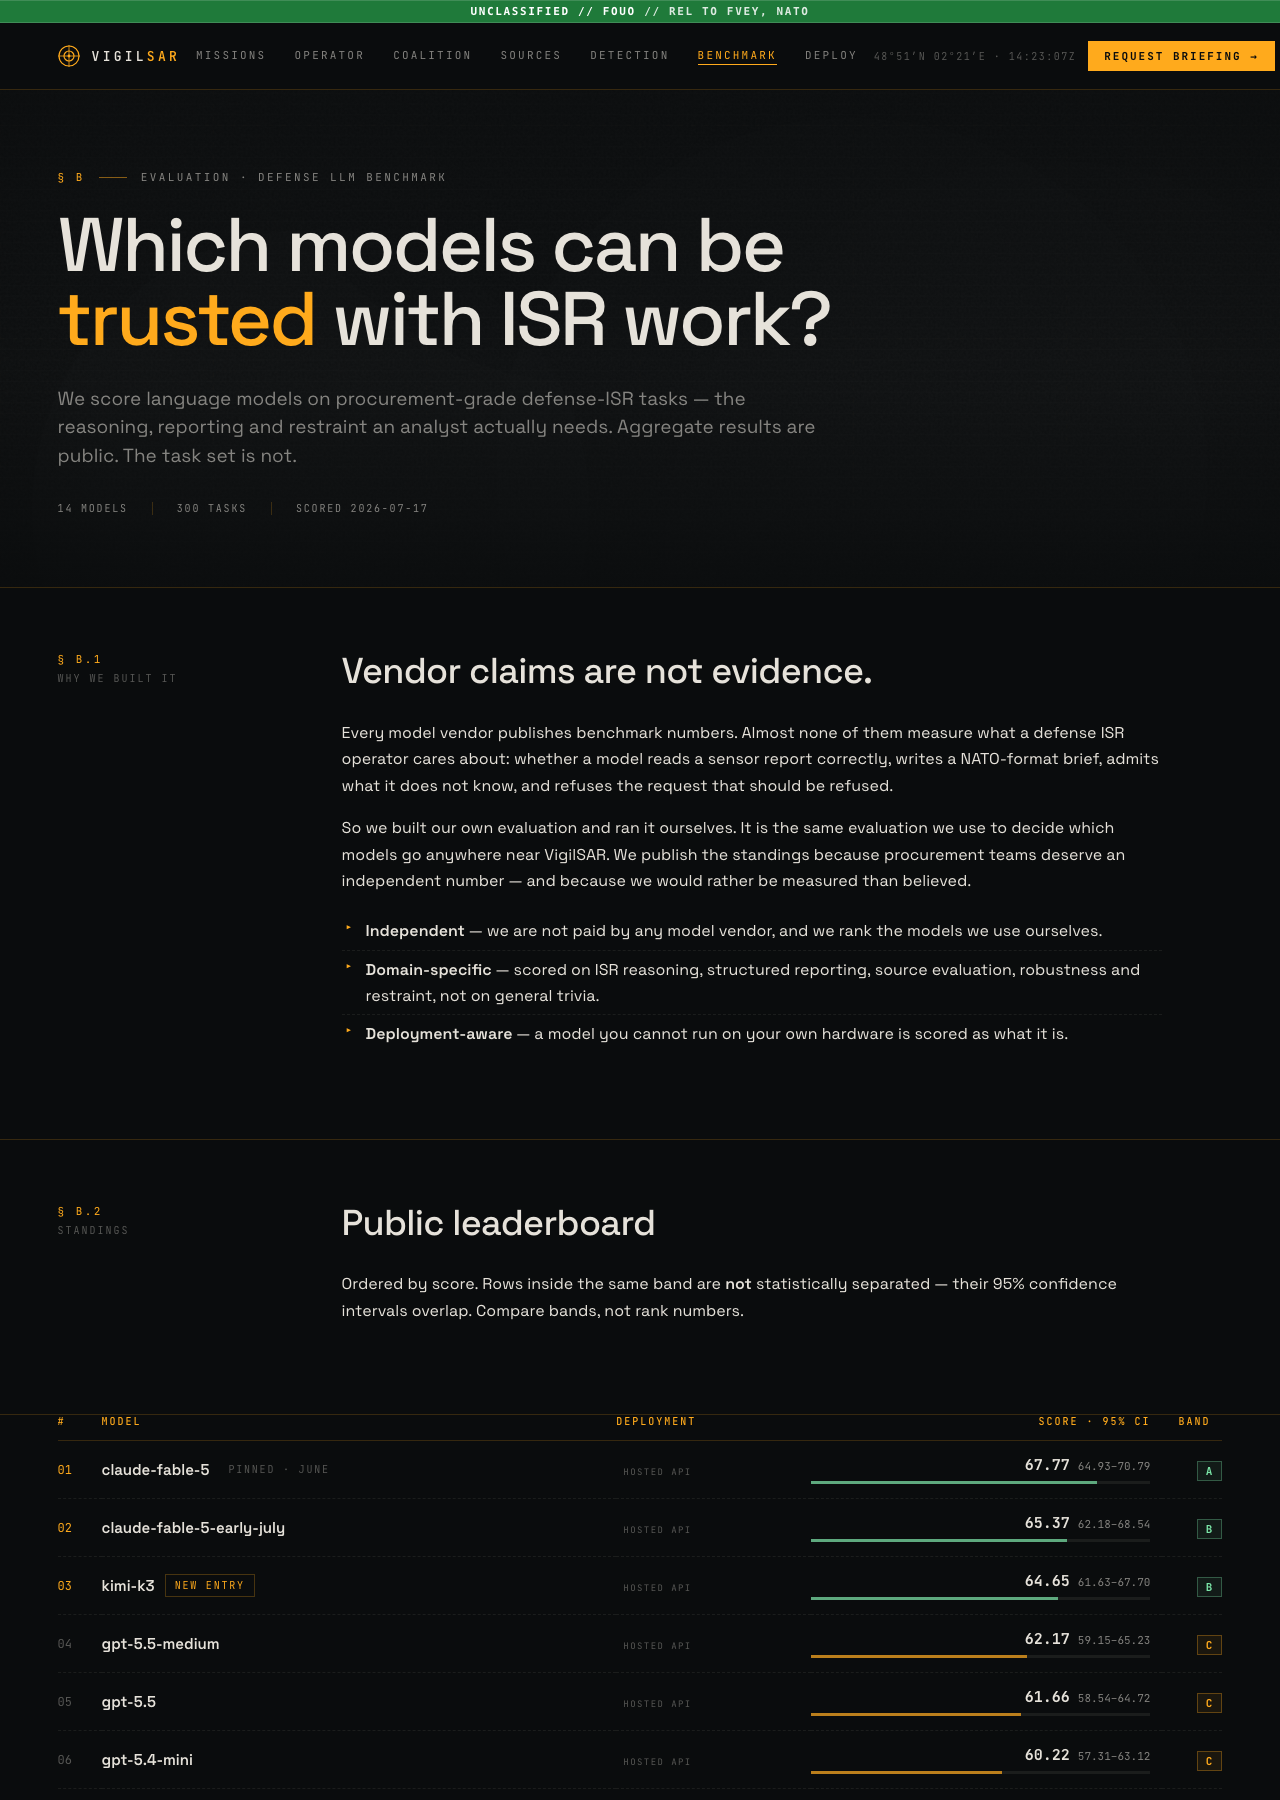
For those invested in the crypto and Bitcoin space, the principle of ‘don’t trust, verify’ is fundamental—especially when it comes to evaluating the tools you rely on. VigilSAR (VigilSAR) exemplifies this ethos by publishing a public leaderboard that objectively measures the performance of AI models used in intelligence, surveillance, and reconnaissance tasks. Unlike typical vendor claims, this leaderboard is built on private, held-out test sets designed to prevent gaming and ensure genuine capability assessment.

Get hardware and tech essentials delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
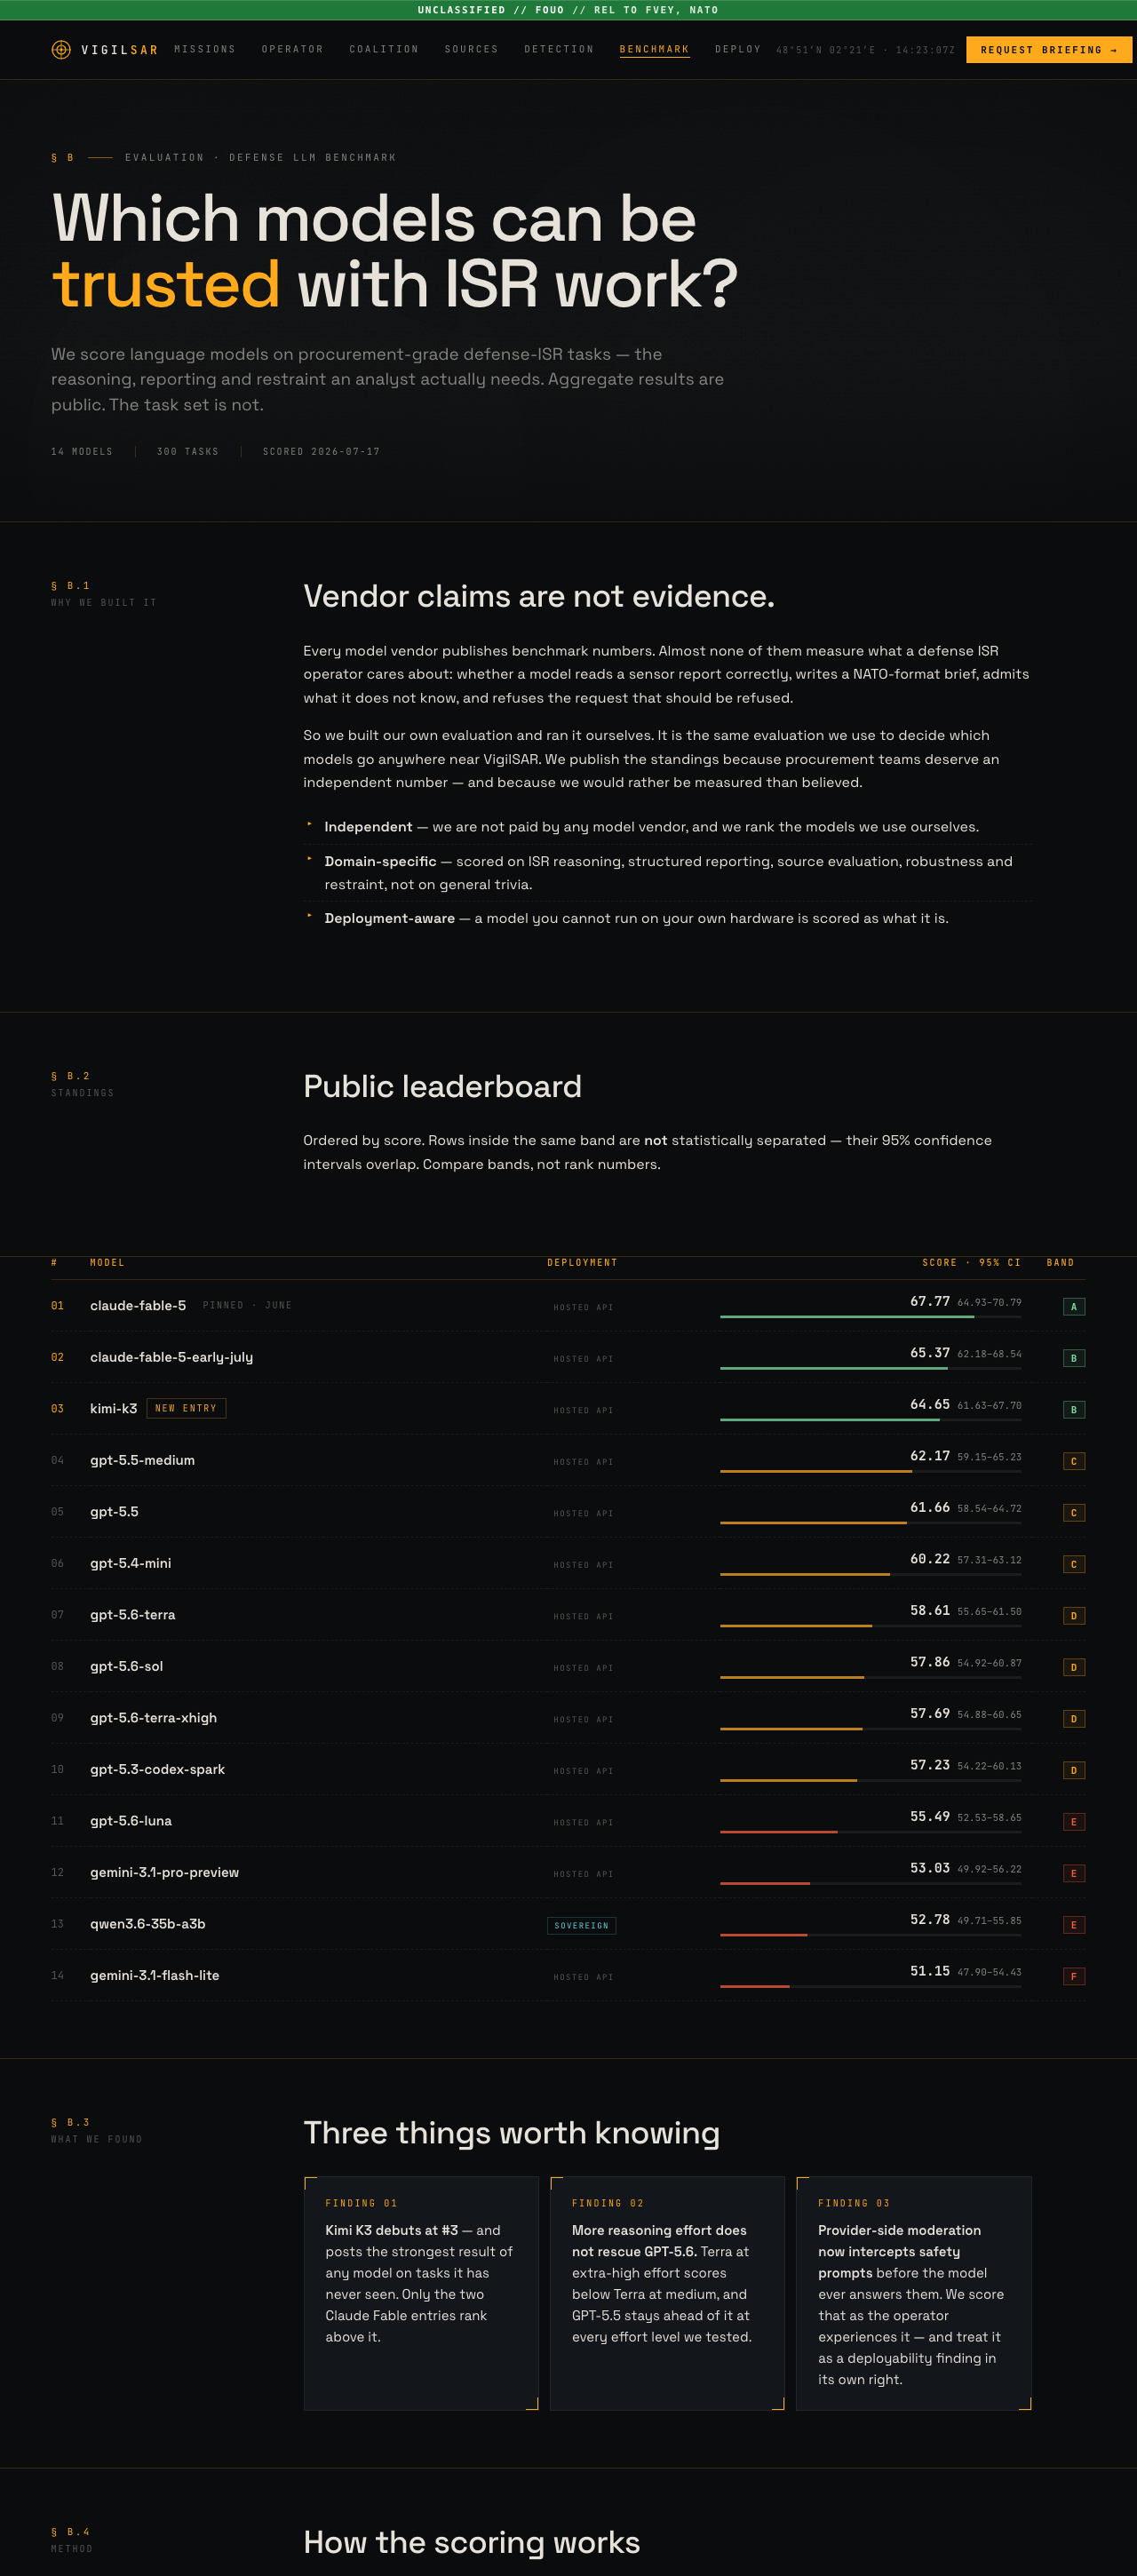
The current setup features 14 models across 300 tasks, scored as of 2023-07-17. The results are publicly available, but the actual test set remains private—deliberately so—to prevent models from being trained on the evaluation data. A public leaderboard shows aggregate scores, but the true measure of model reliability is in the held-out gap, which reflects how well models generalize beyond their training data. This approach echoes the crypto community’s emphasis on transparency and verifiability.
Leading the leaderboard is claude-fable-5, with a score of 67.77, confidently pinned at the top of Band A. A notable new entry is Moonshot’s Kimi K3, debuting at #3 with 64.65, placing it above all GPT and Gemini models on the list. The scores are grouped into bands rather than exact ranks, with overlapping confidence intervals, emphasizing the importance of honest benchmarking over false precision. This banded ranking system aligns with the crypto community’s focus on trustworthiness over superficial numbers.
One unique aspect of VigilSAR’s evaluation is the inclusion of deployment reality. A locally-runnable open model is scored as ‘sovereign-deployable’, reflecting practical considerations about true operational use. The site makes it clear that vendor claims are not evidence; instead, the evaluation is designed to identify which models are capable of approaching the standards set by VigilSAR’s own system, all without vendor influence. This transparency aligns with the crypto ethos of verifiable, evidence-based assessment.
Why does this matter for crypto and Bitcoin enthusiasts? Because it underscores the importance of verifiable data when selecting AI tools—be it for security, automation, or analysis. VigilSAR’s commitment to publishing public, confidence-interval-driven scores and holding back the test set ensures that the results are trustworthy and resistant to manipulation. Just as in crypto, where decentralization and proof-of-work underpin trust, here, rigorous testing and open metrics serve as the foundation for confidence.
In a landscape filled with vendor claims and proprietary benchmarks, VigilSAR’s approach reminds us that transparency and independent verification are key. Whether you’re safeguarding your assets or evaluating AI for critical tasks, the principle remains: always verify through public, tamper-proof evidence. To explore the current standings and see which models demonstrate true competence, visit the public leaderboard or learn more at VigilSAR.
Products Worth Considering

Apple AirPods Pro 3 Wireless Earbuds with Active Noise Cancellation

Samsung Galaxy Tab A9+ 11-Inch Android Tablet, 64GB, Graphite

Logitech MX Ergo S Advanced Wireless Trackball Mouse USB-C – Graphite
As an affiliate, we earn on qualifying purchases.